Applying Rahul Garg's Feedback Flywheel to Agent Workflows
Rahul Garg described a feedback flywheel on Martin Fowler's site. Retained failures and shared instructions can inform tested updates to an agent workflow.
TL;DR
- On April 8, 2026, Rahul Garg published the Feedback Flywheel on Martin Fowler's site: convert individual AI interactions into collective team improvement. Four signal types. Four shared artifacts. The metric is declining instances of why did the AI do that.
- Context, instruction, workflow, and failure signals feed priming docs, commands, playbooks, and guardrails. Cadence runs after each session, at standup, at retro, and quarterly.
- Retained failure records and shared instructions can inform proposed workflow updates. Teams must write and test changes rather than assuming files act as automatic runtime configuration.
- Captured failure signals do not automatically create guards on the next run. Callers can manually turn repeated issues into tested guardrails, budget limits, or rate limits.
On April 8, 2026, Rahul Garg published a detailed article on Martin Fowler's site describing a pattern called the Feedback Flywheel, a system for converting individual AI interactions into collective team improvement.
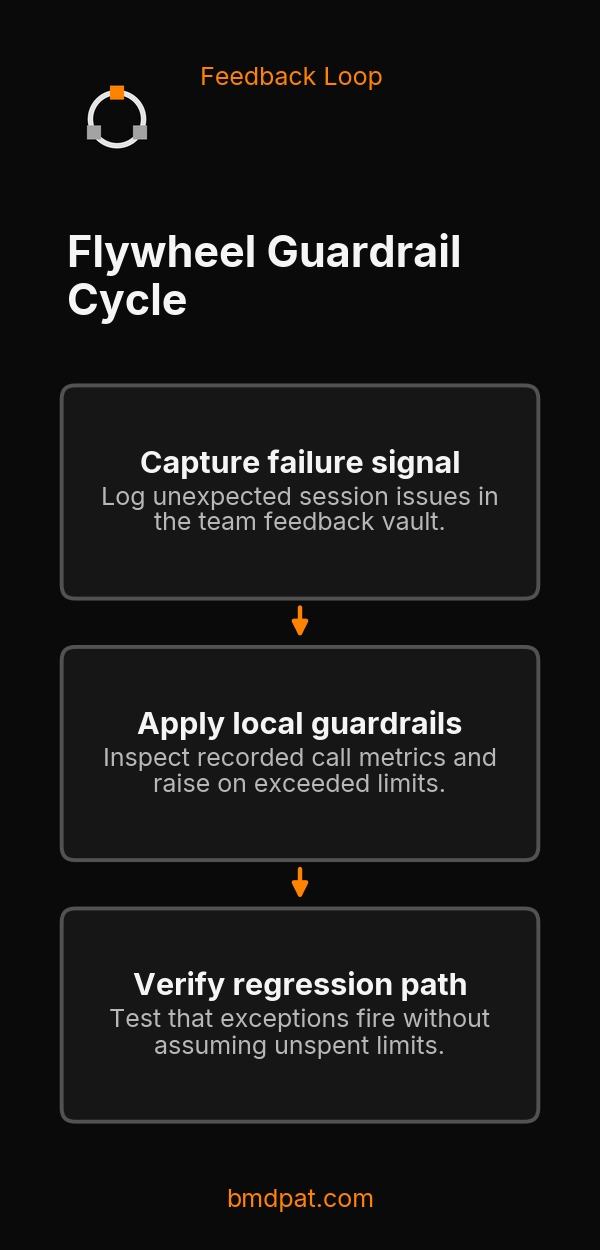 Open full-size image (opens in new tab)
The article highlights a common problem: AI interactions generate useful signals, but teams often discard that information instead of routing it into shared artifacts.
This post describes Garg's framework from Fowler's site, outlines our current workflow, and explains how capturing signals requires validated changes and tested reuse to count as real improvement.
What the Framework Describes
The Feedback Flywheel described by Garg on Fowler's site has two layers: signal types and shared artifacts.
The four signal types identified in the article:
- Context signals, facts about your codebase, domain, or project that the AI needs to do good work
- Instruction signals, prompts, commands, and phrasings that reliably produce good output
- Workflow signals, multi-step sequences that work well end-to-end
- Failure signals, cases where the AI did something wrong, so you can guard against it
Those signals feed into four shared artifacts:
- Priming docs, shared context files the whole team pulls into every session
- Commands, reusable prompt templates anyone can invoke
- Playbooks, documented workflows for recurring tasks
- Guardrails, explicit constraints that prevent known failure modes
The cadence runs at four levels: after each session, at standup, at retro, and quarterly. The key metric proposed in the article: declining instances of "why did the AI do that?"
What We Built
Our workflow uses general shared instructions, knowledge sources and syntheses, queues and reports, alongside AgentGuard checks.
Layer 1: The Vault (Signal Capture)
We track operational observations across knowledge sources, queues, and run reports rather than a dedicated feedback folder. The system records four capture questions:
- What the prompt was
- What the output was
- Whether it worked
- What to do differently next time
This aligns with the four signal types from Garg's article. Context signals feed shared project instructions and knowledge syntheses. Instruction signals update shared prompts and task guidance. Workflow signals update run queues and testable scheduled skills.
Shared instructions, knowledge syntheses, queues, and reports support this workflow. Tasks perform task-specific reads or generate task-specific reports, though files are not universally ingested at startup as runtime configuration and individual tasks do not automatically update shared memory or queues.
Layer 2: Task Execution and Review
Each scheduled task follows its own input and output contract. A task may read shared instructions or write relevant reports, queues, and generated views. Shared memory and queue updates occur only when a task is assigned them, not on every run. Passing output forward lets subsequent runs inspect prior results, but changes to core instructions still require validation.
Signal captured → shared artifact updated → next agent reads it → evaluated reuse
Capturing output does not guarantee better performance on its own. Retained run failures and logs can inform tested changes, but captured observations and approved instruction updates require tests and later useful reuse without guaranteed baseline gains.
Layer 3: AgentGuard (The Guardrail Layer)
AgentGuard provides programmatic guardrails. It enforces runtime checks based on recorded usage:
- Budget limits, inspect recorded cost and token totals and raise exceptions when limits are reached
- Token limits, record token consumption and halt subsequent steps after limit breaches
- Time limits, cooperative timeouts check elapsed execution time across steps
- Rate limits, track call frequency to mitigate rapid looping
This maps directly to the guardrail artifact. The difference: AgentGuard enforces guardrails programmatically, not through documentation alone. A failure signal does not stay as a passive note; it can inform a proposed test or guard condition that checks recorded metrics on subsequent runs. Helper checks inspect recorded usage rather than future call costs, and consume records after a call finishes and may raise only after incurred usage. Cooperative timeouts do not interrupt blocking tools, and guards do not protect against hostile code in the same process, router malware, or credential theft. Unknown model estimates return zero with a warning, so callers must handle unpriced models.
from agentguard import BudgetGuard, TimeoutGuard

budget = BudgetGuard(max_cost_usd=5.00, max_tokens=100_000)
clock = TimeoutGuard(max_seconds=300)

def run_agent_steps(steps):
    results = []
    with clock:
        for step in steps:
            clock.check()
            budget.check()
            # Caller integration (not measurement): step provides actual tokens and cost fields
            step_result = step()
            budget.consume(tokens=step_result.tokens, calls=1, cost_usd=step_result.cost)
            results.append(step_result)
    return results
When a new failure mode is discovered, a guard check can be added. These checks inspect recorded usage after calls or enforce cooperative timeouts, helping catch regressions during subsequent runs.
The Weekly Cadence
| Cadence | Framework Artifact | Our Implementation |
|---|---|---|
| After each session | Priming doc update | Shared instruction and knowledge updates |
| Daily | Standup signal review | Queue and status report reviews |
| Weekly | Retro + playbook update | Reviewing run logs and updating testable skill files |
| Periodic | Strategy refresh | Evaluating validated outcomes and retiring obsolete patterns |
The weekly review provides a regular cycle to evaluate individual session learnings. Teams can review effective prompts as potential templates, and recurring failures can inform proposed tests or guardrails.
Why This Matters for AI Adoption
The Feedback Flywheel outlines a structured approach to share operational patterns and learnings across team workflows.
Garg's article names this pattern clearly on Fowler's site, giving teams a shared vocabulary. That distinction matters: named patterns get implemented, while unnamed patterns stay accidental.
But implementation is where it gets real. Building AI agents that run reliably in production benefits from structured operational artifacts. With these artifacts, each new agent can reference tested patterns and evaluated observations from earlier runs.
What to Build First
If you want to implement a Feedback Flywheel for your team, start here:
Week 1: Create a shared context file. One document everyone pulls into every AI session. Put your domain glossary, common workflows, and "don't do this" notes in it. Update it after every session.
Week 2 (Suggested Sequence): Build a failure log. When an AI output goes wrong, write down what the prompt was and what went wrong. Over time, logged entries can help identify recurring patterns to inform proposed constraints.
Week 3: Add a budget guardrail. If you're running autonomous agents, add a spend limit check before they touch production. The cost of one runaway agent illustrates why catching excessive calls early matters.
Week 4: Run a retro on your AI tooling. What prompts are people reusing manually? Turn them into shared commands. What workflows run every week? Turn them into scheduled agents.
By week 4 you have the initial structure of a feedback workflow, though continued gains require ongoing testing and review.
FAQ
What is the AI Feedback Flywheel? A pattern for converting individual AI interactions into shared team improvement. Four signal types (context, instruction, workflow, failure) feed into four artifacts (priming docs, commands, playbooks, guardrails) on four cadences.
How do you implement it? Start with a shared context file. Add a failure log. Build budget guardrails. Run weekly retros to evaluate learnings for shared infrastructure.
What does AgentGuard have to do with it? AgentGuard implements the guardrail artifact programmatically. Failure signals can inform runtime checks that inspect recorded usage rather than static documentation notes.
Why does it matter? Without shared memory, teams repeat the same mistakes. Capturing feedback and checking runtime limits helps successive runs build on prior operational learnings.
Accompanying prompt
What the prompt does: Reviews agent call paths, configures budget and timeout guards, and tests limit handling without executing network requests. Copy/paste this prompt:
Copy-ready prompt
Paste the exact block into your coding agent.
No article chrome, no footnotes, no formatting drift.
This prompt and every other one we publish live in the free prompt library.
Copy the block above.
To test runtime guardrails and budget checks on your own agent call paths, explore AgentGuard.
FAQ
What are Garg's four signal types?
Context, instruction, workflow, and failure. They feed priming docs, commands, playbooks, and guardrails.
How can teams organize these shared artifacts?
Teams can store instructions and guardrails in structured files, but updates require explicit implementation and testing before agents can use them reliably.
Where do failure signals go?
Failure signals can inform new tests, prompts, or caller-enforced runtime limits. They do not automatically install guards for the next run without code changes.
Get the Local AI Field Kit
Four copy-ready tools now, then one evidence-backed Local AI Lab Note on Friday when there is something worth sharing.
Try the free agent run check firstGet the requested artifact now, then at most one evidence-backed Local AI Lab Note on Friday when there is something worth sharing. One-click unsubscribe. No sponsored placements. Privacy.
Written by
Patrick Hughes
I build BMD and publish measured AI runs, failure reports, and reusable checks. Nashville, Tennessee.
More writing
- 7 min
How to Hire an AI Agent Developer (2026 Guide)
The market is flooded with people claiming to build AI agents. Here's how to tell who can actually ship one, and what questions to ask before you pay anything.
- 7 min
We Built Martin Fowler's Feedback Flywheel Before He Published It
Martin Fowler published a pattern for turning individual AI interactions into collective improvement. We had already built it. Here is how our 12-agent vault system maps to his four signal types.
- 5 min
Software to Control Runaway Agent Loops That Burn Tokens
Stop runaway agent loops with CLI turn caps, graph recursion limits, Python guards, or proxy budgets before token burn exhausts your API credits.
- 5 min
Your local LLM is not a worse Claude. It is a different tool.
Stop scoring your local model on how close it gets to Opus. It is a different tool with a different sweet spot. Here is the line, and which side your work sits on.
- 5 min
Use Owner Gates and AgentGuard to Keep AI Agents Moving
AI agents need two rails before they can run unattended: owner gates for judgment and AgentGuard for spend. Without both, the operator becomes the fallback.