Loading posts
§ 001 / WRITING
What fits, what it costs, and why it is slow
Local LLMs, GPU sizing, GGUF quants, and what AI agents cost. The local-AI numbers come from dated runs on hardware I own. Every other figure names its source.
6
- I Replaced Five Scheduled Tasks with Codex Cron5 min
- Why I Built a Paid GPU Check and Hid the Buy Button5 min
- OpenClaw AI Assistant Latest News 20265 min
- What Does Q4_K_M Mean? GGUF Quantization Decoded5 min
- Q6_K vs Q8_0: Which GGUF Preset Fits Your Setup?5 min
- llama-server ngl: How to Set and Verify GPU Offload5 min
Working with coding agents? Verify their work and protect your acceptance checks.
§ 002 / START HERE
The questions people ask most, answered.
The AI agent build notes
Real costs, real tools, no fluff. One evidence-backed note on Friday when there is something worth sharing.
Get the requested artifact now, then at most one evidence-backed Local AI Lab Note on Friday when there is something worth sharing. One-click unsubscribe. No sponsored placements. Privacy.
§ 003 / LATEST WRITING
 real test output
6 min read
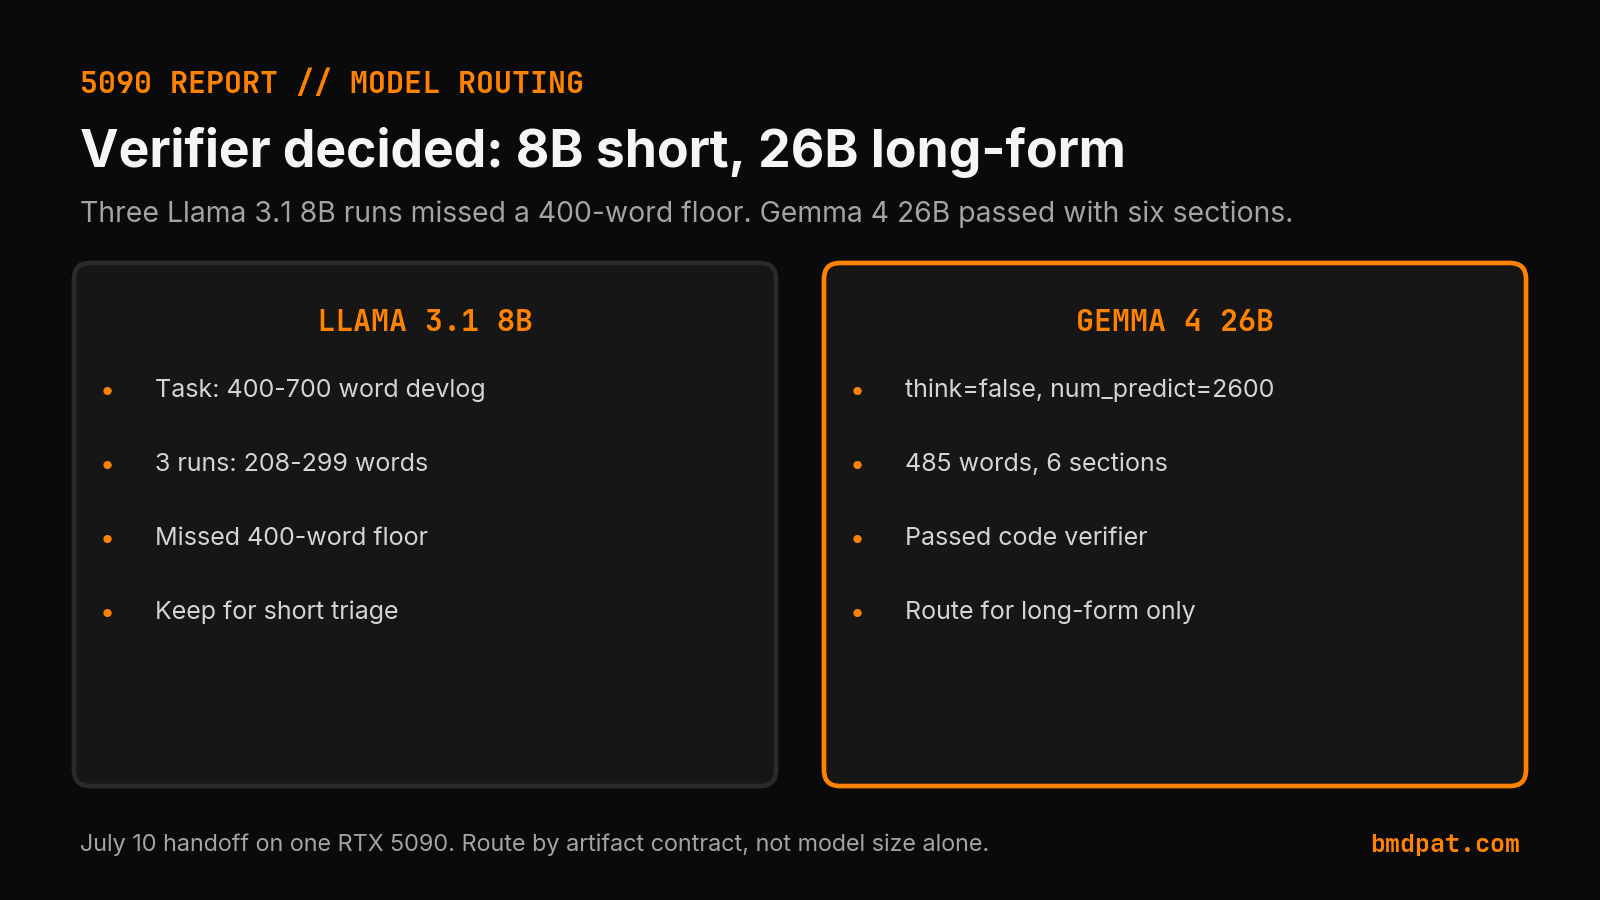
My 8B Model Failed a 400-Word Task
Three Llama 3.1 8B runs missed a 400-word floor. Here is the verifier-driven route that moved long-form synthesis to Gemma 4 26B.
Read the post- 5 min read
I Replaced Five Scheduled Tasks with Codex Cron
On 2026-10-17, I killed five Windows scheduled tasks and moved nightly queues to seven Codex cron jobs. The security audit stayed red across five repos.
- 5 min read
Why I Built a Paid GPU Check and Hid the Buy Button
On 2026-10-24, I shipped a paid GPU purchase review page with the payment link turned off. Here is why dead plumbing beats fake demand data.
- 5 min read
OpenClaw AI Assistant Latest News 2026
OpenClaw release v2026.10.4 repairs sleep restarts and Tlon permissions, following skill discovery, MCP Apps, and R2 backup updates in October 2026.
- 5 min read
What Does Q4_K_M Mean? GGUF Quantization Decoded
Learn the exact meaning of Q4_K_M in llama.cpp, how its mixed tensor precisions work, and how to verify if it fits your consumer GPU VRAM budget.
- 5 min read
Q6_K vs Q8_0: Which GGUF Preset Fits Your Setup?
Compare Q6_K and Q8_0 presets for llama.cpp. See real VRAM allocation, file sizes, and test steps to decide which GGUF quantization fits your card.
- 5 min read
llama-server ngl: How to Set and Verify GPU Offload
Learn how to set -ngl in llama-server, verify GPU layer offload in startup logs, avoid silent CPU fallback, and check device readiness.
- 5 min read
I Rebuilt BMD Desktop Around Queues and Drain
On 2026-10-14, I rebuilt BMD Desktop around queues, cut 63 open requests down to 10, and faced an overnight log full of red security audits.
- 5 min read
Twelve Characters Put My Government Page Live
On 2026-10-03, CI stalled on full disks before a twelve-character string cleared production. Here is how I removed myself from the merge loop.
- 5 min read
Horizon Closed Seven Red, Three Amber, Zero Green
On 2026-10-15, my 90-day horizon closed red across seven bets. Here is what broke in my fleet, what shipped, and how to audit your checks.
- 5 min read
What Does ngl 99 Mean in llama.cpp?
In llama.cpp, ngl 99 sets a numeric cap of 99 layers in GPU memory rather than 99 percent VRAM. Here is how layer offloading works and what to run.
- 5 min read
q4km vs q4ks: which 4-bit file fits?
q4km is Q4_K_M and q4ks is Q4_K_S. For Llama 3.1 8B, the quantize README lists 4.36 GiB for Q4_K_S and 4.58 GiB for Q4_K_M.
- 5 min read
KV Cache Q4 vs Q8 in llama.cpp Explained
Compare q4_0 and q8_0 KV cache options in llama.cpp server. Learn the exact CLI flags, allowed types, defaults, and how to verify output quality.
The AI agent build notes
Real costs, real tools, no fluff. One evidence-backed note on Friday when there is something worth sharing.
Get the requested artifact now, then at most one evidence-backed Local AI Lab Note on Friday when there is something worth sharing. One-click unsubscribe. No sponsored placements. Privacy.