When Tokens Cost 12 Cents Per Million, The Bottleneck Isn't Cost. It's Control.
NVIDIA Blackwell delivers 35x lower cost per token vs Hopper. That makes AI agents cheaper to run and harder to stop. Here's why that flips the runtime guard argument upside down.
TL;DR
- An NVIDIA comparison table presents throughput and calculated token-cost ratios between HGX H200 and GB300 NVL72 under vendor conditions, rather than our direct measurement, universal per-token pricing, or measured same-loop duration.
- Lower per-token cost alone establishes neither completed task quality nor bounded retries, tool-call counts, or loop durations across agent workflows.
- Governance recommendations focus on tracking recorded call counts, repetitive retries, cooperative timeouts, and observed task outcomes in caller code rather than relying on delayed billing notifications.
- Caller-owned runtime checks inspect recorded usage in Python code, but the caller must honor raised exceptions and stop conditions, and records consumed after an incurred response cannot prevent overruns.
Related guides
NVIDIA published numbers that change how AI agent teams should think about cost control.
In NVIDIA's inference comparison (current read 2026-10-22), the vendor table compares HGX H200 with GB300 NVL72 modeled cost per million tokens alongside 90 versus 6,000 tokens/second/GPU. This is a vendor-modeled system comparison, not universal pricing or my own measurement.
If you build AI agents, the instinct is to celebrate. Cheaper tokens means cheaper agents means bigger margins, right?
Wrong direction.
 Open full-size image (opens in new tab)
Cheap tokens make runaway agents worse, not better
Here is what happens when token costs drop.
Your coding agent hits a stuck retry loop. Same tool call, same timeout, same error. When tokens were more expensive, an agent would burn through an account threshold during an extended loop. You noticed when the bill arrived. Painful, but bounded.
With lower token costs, that same loop can run far longer before hitting a spend threshold. The agent continues looping, executing repeated calls before any spend limit trips.
The failure mode did not go away. It got louder.
Budget guards were never about saving money
If you've been pitching runtime guards as a cost control tool, you've been pitching the wrong problem.
The problem isn't the bill. Instrumented retry loops and explicit tests show repeated tool execution under failure conditions. Cheaper tokens do not fix repeated tool execution. Teams address this operational control problem with application-level checks.
Higher token prices did not guarantee safety. Instrumented retry loops show that repeated tool calls accumulated before anyone reviewed invoices.
With lower token prices, teams need local checks in code at the call site.
What governance actually looks like in code
Here is the runtime guard:
from agentguard import BudgetGuard, LoopGuard, TimeoutGuard

budget = BudgetGuard(max_cost_usd=5.00, max_calls=50)
loops = LoopGuard(max_repeats=3, window=6)

with TimeoutGuard(max_seconds=300) as clock:
    for step in agent.plan(task):
        budget.check()
        clock.check()
        loops.check(step.tool, step.args)
        result = step.run()
        budget.consume(calls=1, cost_usd=result.cost_usd)
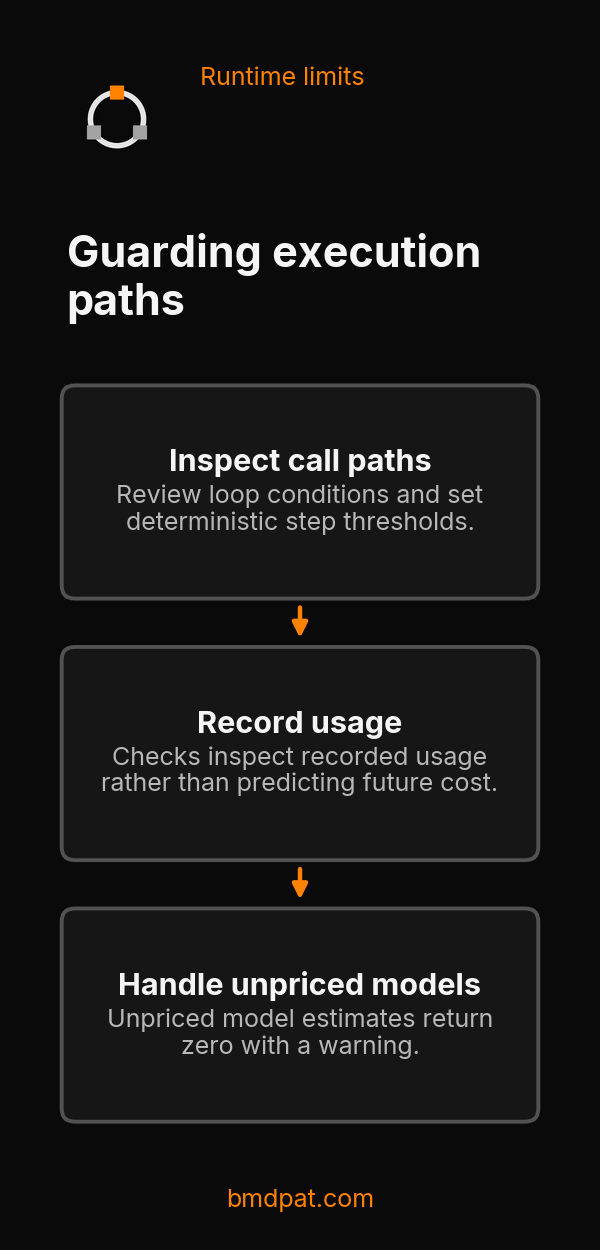
Four rules: a cost ceiling, a call cap, a loop detector, and a clock. These guards provide cooperative runtime checks rather than an immutable security boundary. BudgetGuard.check inspects recorded usage before the next call; an unknown cost can overrun the remaining amount. The consume method records usage after work and may raise after cost is incurred, so the application must honor exceptions. A warning threshold may be crossed by the same incurred call that breaches a limit, with no guaranteed early notice. Unknown model estimates return zero with a warning rather than free usage, so callers must handle unpriced models directly.
This is a sanity ceiling.
Same for max_calls=50. If an agent makes 50 tool calls on a single task, the guard halts before additional calls accumulate.
LoopGuard(max_repeats=3, window=6) catches repetitive retries: the same tool with identical arguments three in a row raises on the third.
TimeoutGuard(max_seconds=300) provides a cooperative timeout across iterations. Cooperative timeouts do not interrupt blocking tools, and helper exceptions can be caught by caller logic.
The pitch update
If you work on AI agent infrastructure, your positioning needs to shift. Here's the old pitch:
"Stop an agent before it burns through an account credit limit."
Here's the new pitch:
"Keep an agent inside the rails you set. No matter how cheap tokens get."
Same product. Different frame. The new frame doesn't depreciate as inference costs drop.
For AgentGuard specifically, this is why we run local-first and zero-dependency. The guards run in your process, not in a hosted gateway. No latency hop. No billing relationship with a third party. The check happens before the request leaves your machine. Note that in-process guards provide cooperative checks, not compromised-code containment, sandboxing, credential protection, or hard invoice caps. They provide no subscription interception for Copilot, Claude Code, or Cursor, and they do not protect against hostile code in the same process, router malware (sampled 428 routers with nine malicious in 2026-04-09 research), or credential theft.
That matters more when tokens are cheap. The cloud gateway economics depend on charging you per request. A zero-dependency SDK doesn't.
Runtime boundaries
Explicit tests show that retry loops and repeated tool calls continue without local checks.
The architecture that survives cheap tokens treats cost as a sanity check, not an external safety mechanism. BudgetGuard checks recorded usage, but consume occurs after incurred usage and can overrun. The application must honor exceptions to stop execution. See pricing and AgentGuard Python.
Accompanying prompt
What the prompt does: Inspects agent execution paths to propose cooperative budget, loop, and timeout limits before runs begin. Copy/paste this prompt:
Copy-ready prompt
Paste the exact block into your coding agent.
No article chrome, no footnotes, no formatting drift.
This prompt and every other one we publish live in the free prompt library.
Copy the block above.
Test local guards on your real call paths. Free, MIT, zero dependencies. pip install agentguard47.
FAQ
What did the NVIDIA inference comparison show?
NVIDIA reported throughput and calculated token-cost ratios between HGX H200 and GB300 NVL72 under vendor conditions, rather than universal pricing, same-loop durations, or our own measurements.
Does lower per-token cost ensure bounded agent execution?
No. Lower per-token cost alone establishes neither completed task quality nor bounded retries, tool-call counts, or cooperative loop completion.
What should caller-owned runtime controls monitor?
Recommended caller-owned controls can track recorded call counts, repetitive retry patterns, cooperative timeouts, and observed task outcomes within caller code.
Get the Local AI Field Kit
Four copy-ready tools now, then one evidence-backed Local AI Lab Note on Friday when there is something worth sharing.
Try the free agent run check firstGet the requested artifact now, then at most one evidence-backed Local AI Lab Note on Friday when there is something worth sharing. One-click unsubscribe. No sponsored placements. Privacy.
Written by
Patrick Hughes
I build BMD and publish measured AI runs, failure reports, and reusable checks. Nashville, Tennessee.
More writing
- 4 min
AI security is now a token-burning contest. Who's watching the bill?
Simon Willison frames AI-assisted security research as proof of work: more tokens in, more bugs found. That's an economic reality. Here's what the spend curve actually looks like and how to put a floor under it.
- 5 min
Your local LLM is not a worse Claude. It is a different tool.
Stop scoring your local model on how close it gets to Opus. It is a different tool with a different sweet spot. Here is the line, and which side your work sits on.
- 5 min
Use Owner Gates and AgentGuard to Keep AI Agents Moving
AI agents need two rails before they can run unattended: owner gates for judgment and AgentGuard for spend. Without both, the operator becomes the fallback.
- 7 min
AI Agent Memory: What Actually Works in 2026
Most agent memory systems add complexity faster than value. This is the small set that actually compounds for one person running a fleet: files, ledgers, and strict verification.
- 4 min
How to Verify Work Done by AI Agents: 5 Falsifiable Claims
Your agent said "done" and the file is unchanged? A clean exit proves it ran, not that the work landed. Record every completion as one of 5 falsifiable claims and let a checker turn the report red.