Study Found 9 Malicious Routers in 428 Tested Proxies
An April 2026 study examined 428 LLM routers and found malicious injection. Proxies can inspect sent requests even when transport encryption protects the link.
TL;DR
- In an April 2026 preprint (arXiv 2604.08407), researchers tested 428 sampled LLM routers (28 paid, 400 free). Nine sampled routers injected code, seventeen accessed test AWS canaries, and one drained ETH.
- Third-party routers are application proxies that can inspect data sent through them even when transport encryption secures the connection. They cannot see traffic routed elsewhere.
- In separate experiments, the researchers evaluated a leaked OpenAI API key alongside weak-router decoy setups to study key abuse and autonomous session behavior.
- In March 2026, LiteLLM investigated a suspected supply chain incident involving unauthorized PyPI releases, citing a suspected Trivy dependency link while initial evidence indicated CI/CD workflows were bypassed. Researchers advise avoiding unmonitored auto-approval mode and routing directly to providers.
Your AI agent calls an API. The API calls a router. The router has full plaintext access to every JSON payload in flight. Third-party application proxies can read and alter payloads despite encrypted network connections. The paper identifies missing client-to-provider cryptographic integrity.
That is how routing operated across the tested proxies. The research team documented security failures across the routers they evaluated.
 Open full-size image (opens in new tab)
The numbers
A team from UC Santa Barbara tested 428 LLM API routers. 28 paid (from Taobao, Xianyu, Shopify storefronts). 400 free (from public communities). The paper is called "Your Agent Is Mine" (arXiv 2604.08407). Here is what they found:
- 9 routers were actively injecting malicious code into responses (1 paid, 8 free)
- 17 routers accessed researcher-owned AWS canary credentials
- 1 router drained ETH from a researcher-owned private key
- 2 routers deployed adaptive evasion triggers (they only inject when they detect certain conditions)
Those results reflect active behavior measured during the research team's evaluation.
How the attack works
LLM API routers sit between your agent and the model provider. They are application-layer proxies. Every prompt, every tool call, every credential your agent passes through the router is visible in plaintext.
The researchers defined two attack classes:
- Payload injection (AC-1): The router modifies the model's response before it reaches your agent. It can inject arbitrary code, change tool call parameters, or redirect actions.
- Secret exfiltration (AC-2): The router copies credentials, API keys, or sensitive data from your agent's requests.
There are also two evasion variants. Dependency-targeted injection only fires when specific libraries are detected. Conditional delivery only triggers under certain conditions, making it harder to catch in testing.
Research findings across sample studies
In the April 9, 2026 v1 preprint, researchers evaluated separate studies measuring leaked credentials, decoy routers, and autonomous sessions:
- 100M GPT-5.4 tokens generated through a single intentionally leaked OpenAI API key
- 2B billed tokens observed across weakly configured decoys in a separate study
- 99 credentials harvested across 440 Codex sessions evaluated in the sample
- 401 sessions of those 440 running in autonomous YOLO mode without per-command confirmation
YOLO here means automatic tool approval without confirmation for each command. The paper does not establish an absence of cost caps or kill switches. When a malicious router intercepts a YOLO-mode session, it controls an agent executing tool actions without per-command confirmation.
The LiteLLM supply-chain compromise
This is not just about routers. In the LiteLLM maintainer security update (March 24, 2026; updated March 30), maintainers reported an ongoing investigation into a suspected supply-chain incident. They believe the compromise originated from a Trivy CI scanning dependency, while initial evidence suggests attackers bypassed official CI/CD workflows to upload unauthorized releases 1.82.7 and 1.82.8 directly to PyPI. Official LiteLLM Proxy Docker images and source installs were not impacted, but environments pulling those specific PyPI packages were exposed.
In a separate threat analysis, a trojanized npm campaign went after AI tool directories to steal the keys those agents run on.
What this means for your agents
If your agent routes through a third-party API proxy, you are trusting that proxy with content routed through its application, including prompts, tool calls, and credentials transmitted in those requests.
How to protect your agents
Three things you can do:
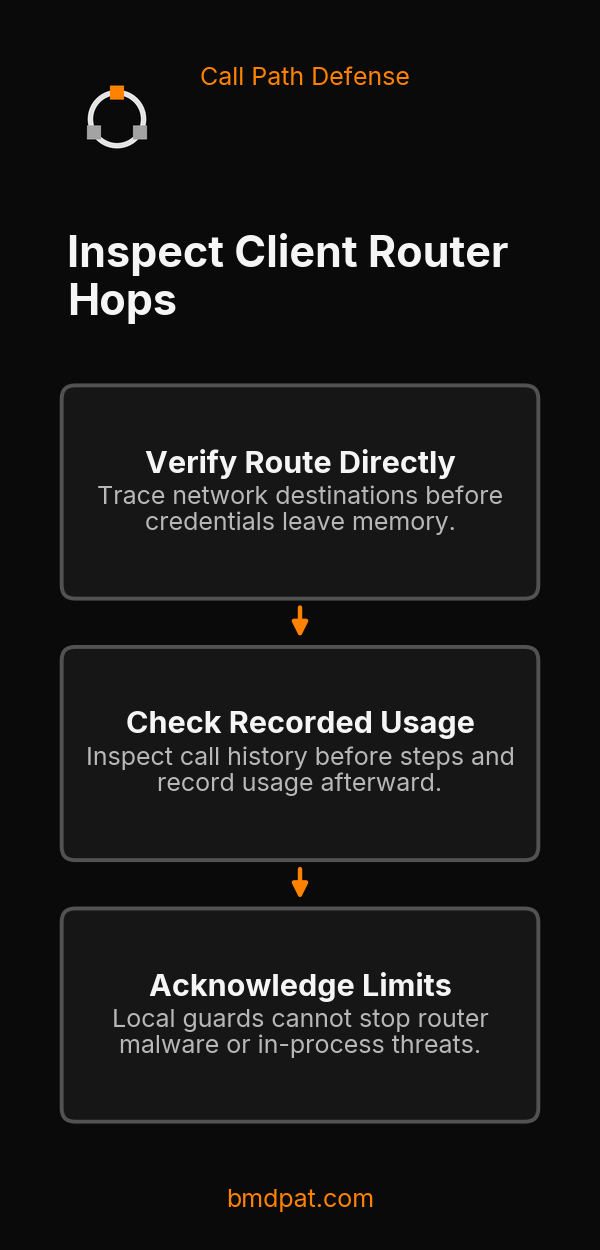
1. Run guards in-process, not at the gateway
A gateway-level guard runs after the proxy has already received your payload. An in-process guard runs inside your agent code before dispatching an external call.
AgentGuard runs in-process with zero dependencies. Helper checks inspect recorded usage rather than future call cost, and consume records usage after the call completes, raising only after usage is incurred.
from agentguard import BudgetGuard, LoopGuard

budget = BudgetGuard(max_calls=10)
loops = LoopGuard(max_repeats=3, window=6)

for step in agent.plan(task):
    budget.check()
    loops.check(step.tool, step.args)
    result = step.run()
    budget.consume(calls=1, tokens=result.tokens)
The imported guards open no network sockets. These guards are plain Python objects in your process. BudgetGuard.check inspects recorded usage before the next call, meaning an unpriced or oversized call can overrun the remaining amount before detection. The consume method records usage after the call completes and may raise an exception after the cost has already been incurred. Your application must honor and handle these exceptions explicitly. A warning threshold can be crossed by the same call that breaches a limit, so early notice is not guaranteed.
These guards are not sandboxing, compromised-code containment, credential protection, or hard invoice caps. Timeouts are cooperative. Unknown model estimates return zero with a warning rather than free usage, and the library does not intercept Copilot, Claude Code, or Cursor subscriptions. In-process guards do not stop router malware, credential theft once secrets leave the process, or hostile code running inside the same runtime.
2. Track recorded usage and iteration limits
In the evaluated sample, 401 out of 440 Codex sessions ran in YOLO mode without per-command approval. Autonomous execution requires explicit tracking of iterations, elapsed time, and recorded token usage. Recorded usage is checked before a call and accounted for after incurred work. Because an individual call can overrun and in-process guards provide no invoice ceiling, applications must handle exceptions when limits are exceeded. See Meta's agent budget control analysis.
3. Test your real call path
Inspect the direct network connection your client makes to the configured endpoint. Local configuration, resolved IP logging, and client TLS verification only check that immediate hop and any explicit local proxy. They cannot reveal or validate hidden server-side relay routes behind a third-party gateway, because the intermediary terminates client TLS before opening its own upstream connection. In staging, test with synthetic canaries rather than real credentials, without assuming clean responses prove an intermediary safe.
The bottom line
In the tested sample of 428 routers, 9 were actively malicious. The researchers demonstrated payload injection and credential exfiltration across those proxies.
Your agents benefit from runtime checks that inspect recorded usage and enforce iteration limits inside your process. These guards do not provide sandboxing, hard invoice caps, or compromised-code containment. They do not replace direct, verified network routes, nor do they protect against credential theft or malicious code executing in the same process.
Accompanying prompt
What the prompt does: Evaluates agent call paths and configures runtime guardrails without executing network requests. Copy/paste this prompt:
Copy-ready prompt
Paste the exact block into your coding agent.
No article chrome, no footnotes, no formatting drift.
This prompt and every other one we publish live in the free prompt library.
Copy the block above.
AgentGuard is an open-source Python SDK for AI agent runtime safety. Budget limits and loop detection that run locally, with zero dependencies.
FAQ
What did the 428-router study find?
In the April 2026 sample, 9 routers injected code, 17 accessed researcher AWS canaries, 1 drained ETH, and 2 exhibited evasion behaviors.
What did the paper examine regarding leaked keys?
The study evaluated leaked-key abuse and separately tested weakly configured routers, showing that exposed keys and unmonitored sessions face rapid exploitation.
What should you change?
Avoid passing sensitive credentials through third-party proxies, prefer direct provider endpoints, and require caller-controlled approval rather than unconfirmed tool execution.
Get the Local AI Field Kit
Four copy-ready tools now, then one evidence-backed Local AI Lab Note on Friday when there is something worth sharing.
Try the free agent run check firstGet the requested artifact now, then at most one evidence-backed Local AI Lab Note on Friday when there is something worth sharing. One-click unsubscribe. No sponsored placements. Privacy.
Written by
Patrick Hughes
I build BMD and publish measured AI runs, failure reports, and reusable checks. Nashville, Tennessee.
More writing
- 3 min
AI Chose Nukes 95% of the Time. Here's What That Means for Your Agents.
Three AI safety papers came out this week. Reading them back to back was jarring. If you run agents in production, this is worth 5 minutes.
- 5 min
57-71% of AI agents leak data between users. Here's what to do.
A June 2026 Mem0 survey of 8 major agent harnesses found that over half of them leak memory across users. Here is why keyword retrieval is a security risk and how to fix it.
- 5 min
57-71% of AI Agents Leak Data Between Users. Here's the Fix.
A 2026 Mem0 survey found 57-71% cross-user memory contamination across major agent frameworks. Here is why it happens and how to stop it.
- 5 min
7% of vibe-coded apps ship with wide-open databases
A 1,764-app audit found 7% had open Supabase databases and 15% of Bolt apps had hardcoded secrets. The fix takes ten minutes.
- 5 min
Your AI Agent's MCP Server Is a Security Hole
1 in 35 GenAI prompts carries high risk of data leakage. MCP makes the attack surface worse. Here's what builders need to know.