OpenAI's guardrails don't control costs. Here's the gap.
OpenAI shipped guardrails in the Agents SDK last month. They validate behavior. They do not enforce spend. Here is the gap and how to close it.
TL;DR
- OpenAI shipped input, output, and tool-call guardrails in the Agents SDK. They inspect what goes in and out at runtime. They answer whether the agent did the right thing. That is not the question that decides your bill.
- No guardrail type takes a dollar limit. Nothing in the SDK stops a run at a spend cap, and no agent function gets its own cost ceiling. That is out of scope. OpenAI is building orchestration and quality control. Budget enforcement is a different layer.
- Your pipeline can pass every guardrail check, keep clean output and approved tool calls, and still make 400 API calls because a retry loop hit an edge case at 2 AM.
- agentguard47 sits below the framework layer. BudgetGuard checks recorded usage against a configured limit, such as $2.00 per run. Provider usage can arrive after a paid call; your code must honor the exception before more work. Guardrails passed is not the same as budget intact.
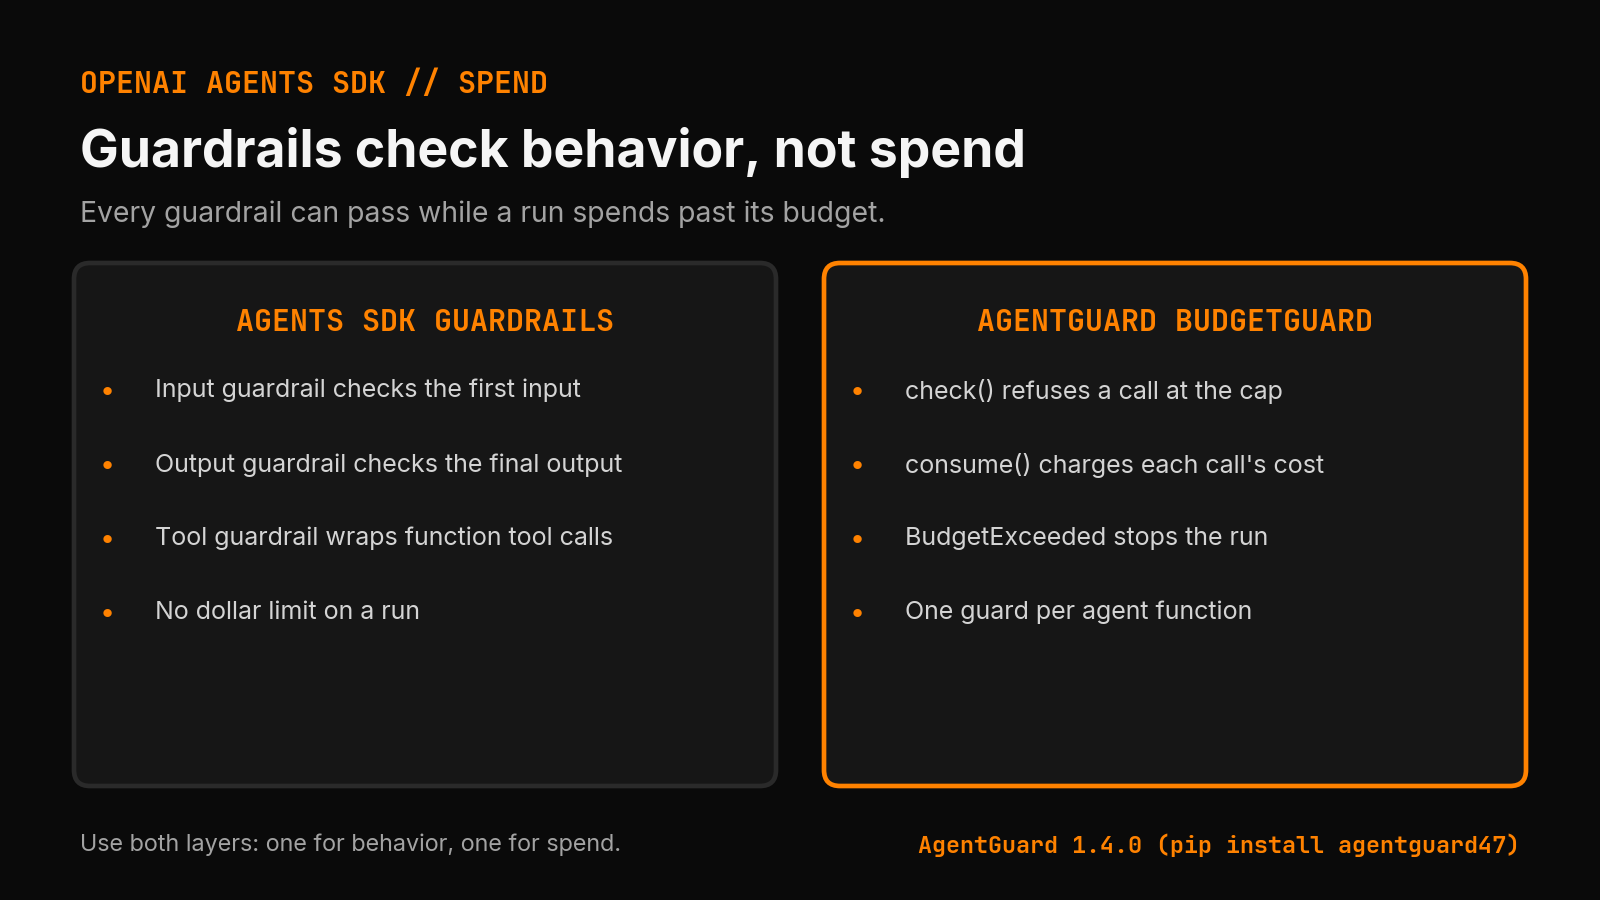
OpenAI's Agents SDK guardrails check what goes into and out of an agent. They do not cap what the agent spends. To stop a run at a dollar limit, put a budget check at the model call, with one guard per agent function.
Correction, October 1, 2026: The first version of this post showed a guard decorator imported from agentguard47. AgentGuard has no guard decorator, and you import it as agentguard. The code below uses the real BudgetGuard API and runs against AgentGuard 1.4.0.
 Open full-size image (opens in new tab)
What do OpenAI's guardrails do?
The guardrails in the Agents SDK are validators. They inspect what goes into and out of your agents at run time. A failed check can trigger a tripwire that stops the run.
- Input guardrails run on the user's input, for the first agent in a run. A tripped check raises
InputGuardrailTripwireTriggered. - Output guardrails run on the final output of the last agent. A tripped check raises
OutputGuardrailTripwireTriggered. - Tool guardrails run before and after a guarded function tool call. They can skip the call, replace its output, or trip. Hosted tools such as
WebSearchToolandFileSearchTooldo not go through them.
These are behavior controls. They answer one question: did the agent do the right thing? That question matters. It is not the question that decides your bill.
Why don't guardrails stop overspend?
No guardrail type takes a dollar limit. The SDK counts tokens in result.context_wrapper.usage, and Runner.run takes max_turns, which raises MaxTurnsExceeded when a run takes too many turns. A turn limit is not a spend limit. Ten turns on a long context can cost more than fifty short ones.
That is a scope choice, not an oversight. The SDK handles orchestration and behavior checks. Budget enforcement is a different layer.
Here is the gap. Say your pipeline passes every guardrail check. The output is clean and the tool calls are approved. Then a retry loop hits an edge case at 2 AM and makes 400 API calls while nobody watches. Every guardrail passed, and the budget is gone.
How do you add a spend cap?
Put the cap at the model call. Give each agent function its own BudgetGuard, check it before each call, and charge it after.
from openai import OpenAI
from agentguard import BudgetExceeded, BudgetGuard, estimate_cost

client = OpenAI()
MODEL = "gpt-4o-mini"


def ask(guard, prompt):
    guard.check()  # refuse the call once this run's cap is spent
    response = client.responses.create(model=MODEL, input=prompt)
    usage = response.usage
    guard.consume(
        tokens=usage.total_tokens,
        calls=1,
        cost_usd=estimate_cost(MODEL, usage.input_tokens, usage.output_tokens),
    )
    return response.output_text


def run_analyzer(task):
    guard = BudgetGuard(max_cost_usd=2.00)  # 2 dollars per run, hard stop
    risks = ask(guard, f"List the risks in this task: {task}")
    return ask(guard, f"Rank these risks by cost: {risks}")
When the run's total passes 2 dollars, consume raises BudgetExceeded. Once the total reaches the cap, check refuses the next call before it goes out. The call that crosses the line still bills, so set the cap a little under the most you will pay.
Catch the error where you call the agent, and decide what happens next:
def analyze_or_escalate(task):
    try:
        return run_analyzer(task)
    except BudgetExceeded as exc:
        print(f"analyzer stopped: {exc}")
        return None  # send the task to a person
estimate_cost reads the AgentGuard price table. Check that your model is in it. For a model the table does not know, it returns a cost of zero with a warning, and a cap fed zero never trips.
Why one guard per function? You create the guard inside the function, so each run starts with its own ceiling, and one runaway run cannot spend the next run's budget.
Does this work with the Agents SDK?
The guard counts what you charge to it, so it works wherever you can read token usage. With a raw openai client, charge each response as above. With the Agents SDK, read result.context_wrapper.usage after each run and charge the guard with its totals. That stops the next run, not the turn in progress, so keep max_turns low as well.
For the full setup with tracing and patched clients, see AI agent cost control with AgentGuard in Python.
Which layer handles what?
Use OpenAI's guardrails for behavior: input checks, output checks and tool approval.
Use a budget guard for spend: a dollar cap per agent function, a hard stop when a run passes it, and a running total of what each run cost.
They are different layers, not rivals. One asks whether the agent behaved. The other asks whether it stayed in budget. You need both answers. For a real case of the second failure, see Your AI Agent's Retry Loop Is a Cost Bug Waiting to Happen.
How do you install AgentGuard?
pip install agentguard47
Then import it as agentguard, as in from agentguard import BudgetGuard. The package name and the import name differ, so copy both lines as written.
Accompanying prompt
What the prompt does: It finds the agent functions in your code that have behavior checks but no spend cap, and writes a per-run dollar cap for each one.
Copy/paste this prompt:
Copy-ready prompt
Paste the exact block into your coding agent.
No article chrome, no footnotes, no formatting drift.
This prompt and every other one we publish live in the free prompt library.
Copy the block above.
Put a dollar cap on your first agent function: AgentGuard
FAQ
What do OpenAI Agents SDK guardrails actually do?
They validate input, output, and tool calls. Behavior controls. They do not track spend.
What is missing for cost control?
No dollar limit on a run and no per-function cost ceiling. Guardrails check behavior, not spend.
What failure still gets through?
A retry loop at 2 AM that makes 400 API calls while every quality guardrail still passes.
Get the Local AI Field Kit
Four copy-ready tools now, then one evidence-backed Local AI Lab Note on Friday when there is something worth sharing.
Try the free agent run check firstGet the requested artifact now, then at most one evidence-backed Local AI Lab Note on Friday when there is something worth sharing. One-click unsubscribe. No sponsored placements. Privacy.
Written by
Patrick Hughes
I build BMD and publish measured AI runs, failure reports, and reusable checks. Nashville, Tennessee.
More writing
- 4 min
agent-sre on PyPI: what SRE for AI agents actually means
Microsoft just shipped agent-sre on PyPI. Seven packages: SLOs, error budgets, circuit breakers. Here is what it does, what it does not, and why solo builders still need agentguard47.
- 6 min
How to Close the AI Agent Cost Gap at the Call Site
The cost gap between what an AI agent could cost and what it does cost is 40%. You close it at the call site, not in a dashboard. Here is how.
- 8 min
Stop Runaway LLM Spend: AI Agent Cost Control (Python)
One bad loop and an AI agent burned $200 in minutes. AgentGuard is a Python SDK that enforces hard cost limits at runtime, here is how to ship it.
- 4 min
Missing AI agent cost data is not zero
A spend ledger that counts missing billing data as $0 hides exactly the unattended agent spend you built it to catch.
- 4 min
When JPMorgan's AI bill goes up, who controls it?
JPMorgan turned on AI for 250k people. The quiet line is that the usage racks up fees. Here is how to control the bill before it arrives.