AI Cafe Napkin Orders and What Runtime Limits Can Do
An AP report noted cafe stock errors. If callers handle raised exceptions after recorded usage, checks can stop later orders but cannot block a single overage.
TL;DR
- According to an AP report, an AI-run cafe in Sweden had stock ordering errors including 6,000 napkins while bread deliveries varied due to missed deadlines.
- The AP report noted the cafe faced stock issues and reported limited memory as an explanation, rather than an incentive to buy cheap items.
- AP reported stock errors without establishing missing controls. When callers honor raised exceptions after recorded usage, runtime checks help stop subsequent orders.
- Recorded usage checks evaluate prior completed orders before the next call. Callers must handle raised exceptions to halt work; checks do not reserve funds in advance.
A purchasing agent deployed at a cafe in Sweden accumulated 6,000 napkins, while bread deliveries sometimes lapsed when the system missed daily bakery deadlines. On May 11, 2026, the Associated Press reported on the experimental cafe, where an AI manager oversaw inventory and placed supplier orders.
Here is how runtime guards contain subsequent calls, where per-order overshoot can still occur, and what runtime budget checks do not solve.
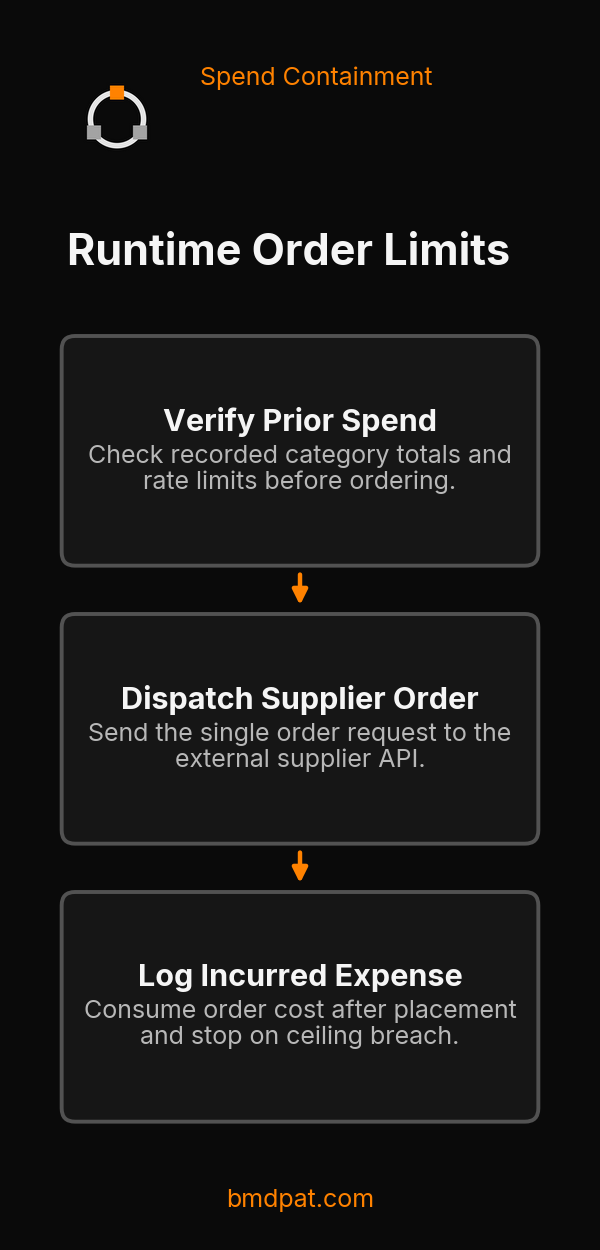 Open full-size image (opens in new tab)
What happened in the ordering loop
Autonomous purchasing workflows highlight the practical need for proposed safeguards, including category boundaries, daily spend limits, quantity checks, and manual review thresholds.
In reporting from the Associated Press, Andon Labs staff member Hanna Petersson described the ordering issues as likely caused by a limited context window forgetting prior orders. The account noted that much of the cafe's depleted cash went toward one-time setup costs rather than napkins alone. The dispatch summarized basic operational instructions in paraphrase, but did not disclose a verbatim prompt, unit-cost incentives, or upstream warning errors.
Proposed checks for autonomous loops
- Cumulative spend ceilings that inspect recorded usage on the agent process, recognizing that an incurred order can cross a ceiling before consumption is recorded and the application must honor raised exceptions.
- Category boundaries to restrict repetitive item purchases.
- Anomaly triggers for repeated orders within the same time window.
- Spend velocity checks and manual review thresholds before order execution.
Runtime guards can halt future calls once recorded usage exceeds configured ceilings, but they do not alter prior decisions or undo placed orders.
Containing future calls at runtime
This is AgentGuard, the runtime budget library I maintain. The shape is the point, not the brand. Any equivalent works.
from agentguard import BudgetGuard, RateLimitGuard

daily = BudgetGuard(max_cost_usd=200.00, warn_at_pct=0.8, on_warning=alert_slack)
by_category = {
    "napkins": BudgetGuard(max_cost_usd=20.00),
    "paper_goods": BudgetGuard(max_cost_usd=40.00),
}
rate = RateLimitGuard(max_calls_per_minute=10)

def place_order(category, sku, usd):
    daily.check()
    by_category[category].check()
    rate.check()
    supplier.order(sku)
    daily.consume(calls=1, cost_usd=usd)
    by_category[category].consume(calls=1, cost_usd=usd)
Here is how each component behaves:
daily = BudgetGuard(...)usesdaily.check()to inspect cumulative recorded usage before the loop executes another call. If an order cost is unknown before dispatch, that call can overrun the remaining allocation before logging occurs. Once recorded usage reaches or exceeds the ceiling,check()raisesBudgetExceeded.by_category["napkins"]provides later-order containment rather than a pre-authorized purchase amount gate. Callingconsumeafter an order completes records the cost and raisesBudgetExceededif the limit has been breached. Because the purchase executes beforeconsumeruns, a single order can overshoot the allocation. Blocking that overshoot requires a separate pre-authorization gate, which this code does not implement.RateLimitGuard(max_calls_per_minute=10)limits call frequency to mitigate rapid retries.- The guards raise exceptions that the application must honor. Catching
BudgetExceededand continuing leaves the loop uncontained. on_warning=alert_slacktriggers a callback only if recorded usage crosses the warning threshold without breaching a limit. A single call that breaches the budget raises before warning checks run, so there is no guaranteed callback or early notice.
The guards track state in memory for the life of the process. For limits that persist across restarts, BudgetGuard accepts external storage and time windows.
What this does not solve
Runtime budget rails operate at the application layer. Several boundaries remain outside their scope:
- Selection and ordering logic. The wrapper does not fix model reasoning or item selection. Budget caps halt future recorded calls, but they do not correct flawed decisions.
- Irreversible external actions. Supplier orders cannot be recalled once dispatched. The wrapper halts future calls after costs are recorded, but cannot undo placed orders. Human review on orders above a set threshold requires a separate pre-authorization workflow.
- Security and environment boundaries. These guards are not compromised-code containment, sandboxing, credential protection, or hard invoice caps. Timeouts are cooperative, and the library does not perform Copilot, Claude Code, or Cursor subscription interception.
- Cost estimation limits. Unknown model estimates return zero with a warning, not free usage.
Structuring external action loops
When an agent loop interacts with APIs that incur financial charges or mutate external state, apply defensive limits directly to the dispatch path. Define category ceilings, track cumulative spend, and require human review for orders above defined thresholds.
Instrument and test call paths with guards before deploying loops to production environments.
Incident tracking
The agent47 repository maintains an incident log for autonomous workflows. The Sweden cafe incident highlights operational risks when autonomous loops run without proposed safeguards like category limits, recorded spend checks, or tracking recent order history.
AgentGuard provides a runtime spend tracking layer. It will not rewrite prompt logic, but it halts subsequent calls once recorded usage meets your configured ceiling.
Related: Meta token usage and agent budget control | OpenAI's guardrails don't control costs
Accompanying prompt
What the prompt does: Audits an agent ordering loop to propose multi-tiered budget guards and rate limits across spending categories. Copy/paste this prompt:
Copy-ready prompt
Paste the exact block into your coding agent.
No article chrome, no footnotes, no formatting drift.
This prompt and every other one we publish live in the free prompt library.
Copy the block above.
FAQ
What did the cafe agent actually do?
According to AP reporting, the cafe had stock ordering errors resulting in 6,000 napkins, with bread deliveries affected by missed deadlines and limited memory.
Did reporting establish missing controls behind the cafe orders?
No. AP reported repeated ordering errors and missed delivery deadlines without verifying missing controls. Separate runtime checks require callers to handle exceptions to halt later orders.
How do runtime ordering checks handle automated purchase thresholds?
Checks inspect prior recorded consumption before the next order. If the caller honors raised exceptions, later calls stop, but an individual order can still exceed the threshold.
Get the Local AI Field Kit
Four copy-ready tools now, then one evidence-backed Local AI Lab Note on Friday when there is something worth sharing.
Try the free agent run check firstGet the requested artifact now, then at most one evidence-backed Local AI Lab Note on Friday when there is something worth sharing. One-click unsubscribe. No sponsored placements. Privacy.
Written by
Patrick Hughes
I build BMD and publish measured AI runs, failure reports, and reusable checks. Nashville, Tennessee.
More writing
- 5 min
I gave an autotrader $360 and 30 days. I am not adding live money yet.
The May 14 autotrader review is done. The account is up 7.7% before compute, still negative after compute, and still lagging SPY and BTC. Decision: keep V2 paper-only, add no new live money, and revisit after the next scorecard.
- 6 min
Your AI Agent Will Eventually Delete Prod
PocketOS lost their production database backups to a Cursor agent. Here's what runtime spend rails actually catch, what they don't, and the layered defense your agents need before production.
- 7 min
AI Agent Safety: Findings from Mythos, Apollo, and Payne
Studies show agent behaviors under specific test setups. These conditions and limits inform how teams review agent workflows without predicting production runs.
- 5 min
Your local LLM is not a worse Claude. It is a different tool.
Stop scoring your local model on how close it gets to Opus. It is a different tool with a different sweet spot. Here is the line, and which side your work sits on.
- 5 min
A verifier loop beats a faster local model
Local LLMs are useful when the loop proves the output, not when the benchmark looks good. This is the small gate I use before a local coding agent gets more rope.