My sandbox passed two tests. The full run was unproven.
I repaired a Windows agent launcher on September 17. Shell commands and two tests passed. That still did not prove the whole nightly queue could finish.
I asked for the failures in my published devlog to be fixed on September 17, 2026. The queue sweep had stopped before it could run its commands. Changing the provider order had not fixed that.
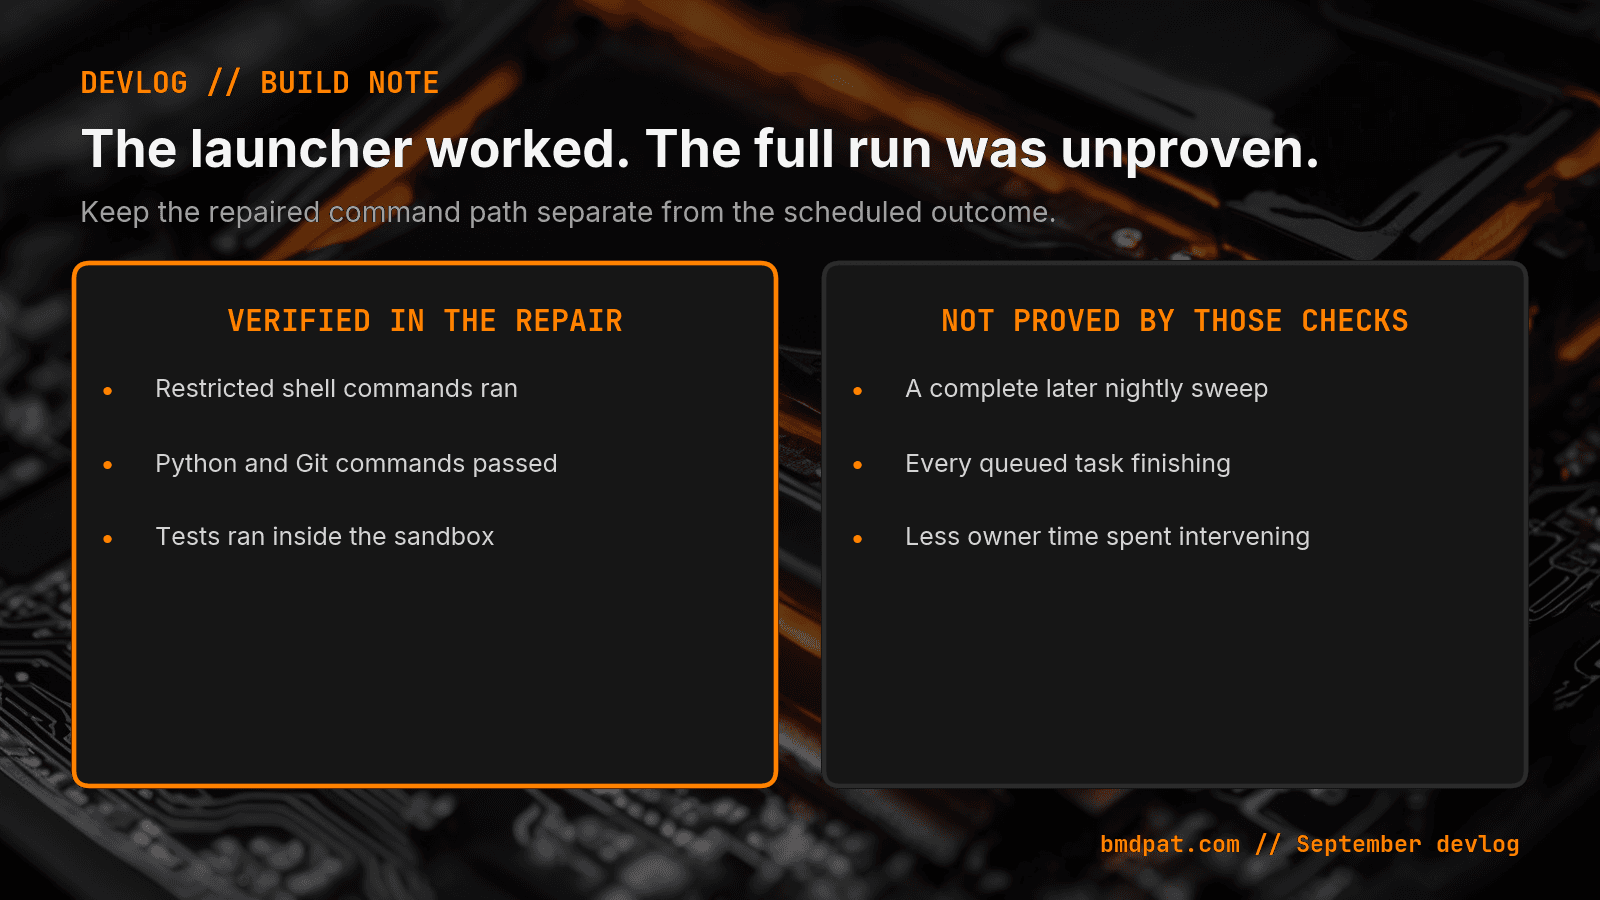
By the end of the repair, Codex could run shell commands and two tests inside the restricted Windows environment. The blog was live too. I still did not have proof of a complete later nightly sweep.
What stopped the queue sweep?
The failed sweep used Antigravity inside a Windows sandbox. Its launcher hit a desktop permission error. It could not start the child commands needed to inspect files, run Python, use Git, or test changes.
That put the failure before the work I wanted done. A model response could not tell me whether the queue had moved. The launcher had to run a command first.
I had already written about moving four jobs to Gemini. That post described September 16. Its unresolved sandbox failure was still a real task when I read it the next day. I wanted the defect repaired, then checked.
What changed in the sandbox?
Codex changed the default sandbox provider order to Codex, then Claude. The ordinary jobs moved to Gemini kept their routing. This was a repair to the restricted queue runner, not a reversal of every provider change.
The Windows restriction stayed in place. The repair did not grant the launcher more permission to create a desktop. It used a provider path that could run the required commands within the existing boundary.
The first command probe confirmed the low-integrity token and returned the expected Python output. Git ran too. Then the test probe found another problem: the test temporary directory pointed outside the sandbox.
The runner now puts that directory inside the sandbox alongside the other temporary directories. A fresh model-driven test run passed two tests with exit code zero. That was the evidence I had wanted from the launcher repair.
Why was that still short of a nightly result?
The two tests proved a specific path: start the agent, run commands, and execute tests inside the restriction. They did not exercise every queue task or prove that a later scheduled sweep finished.
The September 17 queue review made that limit concrete. It reviewed 98 cards. Two were done, 37 were held, and 59 needed a decision. Reviewing a card did not turn it into shipped work.
I have written about checking an agent's output before. This repair gave me another small result to keep separate from the larger claim. I could say the launcher ran commands. I could not say the entire nightly queue now worked.
What else reached a finished state?
The blog repair produced a public result I could open. The September 16 article went live on September 17 at 12:41 CT. The later readback found its title, image, accompanying prompt, and closing link.
Its writer also kept a usable draft before trying to deploy the image. An image delay would no longer discard the article. That mattered because the draft and its hosted graphic could finish at different times.
The missing showwork evidence archive was recovered too. The repair used the actual merge CI log, package build, document response, and committed receipt. The old local test count remained unverified. Recovering the archive did not make that earlier number trustworthy.
My September 17 record contains both the morning failure and the later repair. The later evidence changes what I can say about the launcher. It leaves the full scheduled run unproven. I wanted fewer reasons to intervene, and I still needed that next run to show whether the repair held.
Accompanying prompt
What the prompt does: Separates a repaired command path from a verified end-to-end scheduled result.
Copy/paste this prompt:
Copy-ready prompt
Paste the exact block into your coding agent.
No article chrome, no footnotes, no formatting drift.
This prompt and every other one we publish live in the free prompt library.
Copy the block above.
Get the Local AI Field Kit
Four copy-ready tools now, then one evidence-backed Local AI Lab Note on Friday when there is something worth sharing.
Try the free agent run check firstGet the requested artifact now, then at most one evidence-backed Local AI Lab Note on Friday when there is something worth sharing. One-click unsubscribe. No sponsored placements. Privacy.
Patrick Hughes
I build BMD and publish measured AI runs, failure reports, and reusable checks. Nashville, Tennessee.
More writing
- 5 min
Gemini first for four jobs. One run finished two tasks.
I moved four recurring jobs to Gemini, then checked what actually finished. One recorded run proved progress. The broken queue sweep stayed broken.
- 3 min
Devlog 2026-07-13: local drive git corruption stalls the q
The nightly queue sweep aborted for the fourth straight night. The root cause is a critical failure in the vault health check. I discovered a private path wo...
- 4 min
When Your Blog Repair Loop Fails 23 Times, Stop Repairing
My blog repair loop chewed on a stale draft for 23 mornings and reported "blocked" every time. The fix was not a smarter retry. It was a TTL and a heal path.
- 6 min
143 pull requests. Zero dollars.
In the week of 2026-08-31 the fleet merged 143 product pull requests. Stripe still read zero. Throughput is the tell, not the win.
- 6 min
A kill rule that expires is not a kill rule
I wrote a kill rule for a paid-path test. Zero orders landed. The card expired into an archive and the dashboard still said ACTIVE.