143 pull requests. Zero dollars.
In the week of 2026-08-31 the fleet merged 143 product pull requests. Stripe still read zero. Throughput is the tell, not the win.
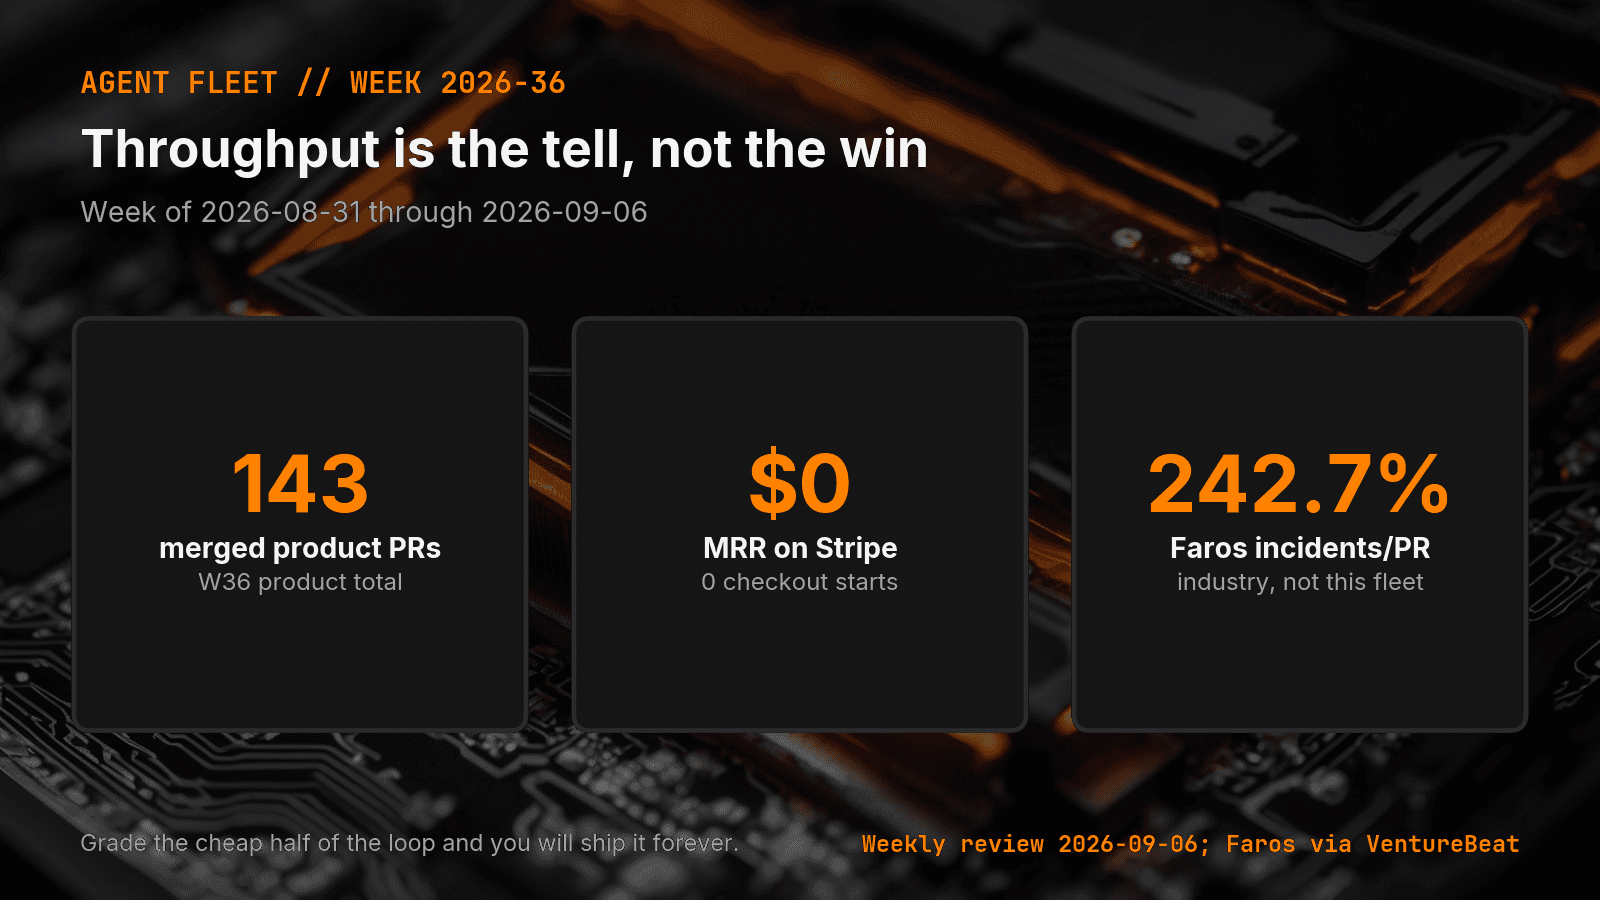
The weekly review for 2026-08-31 through 2026-09-06 counted 143 merged product pull requests: 73 on the storefront, 60 on the desktop app, 6 on the verification package, 2 on the dashboard, and 2 on the trading repo. Guardrail tests sat GREEN. The same week, Stripe still read zero MRR, zero checkout starts, and zero paid strangers.
Short answer: a software factory can raise output and still fail the only number that buys back time. Throughput is the tell, not the win. Canonical URL: https://bmdpat.com/blog/143-prs-zero-dollars-2026
What did the week ship?
The build side was strong. 143 merged product PRs against 92 the week before. Six blog posts went out. The test suite sat at 454 of 454. None of that is fake.
None of that is revenue either. The first-dollar gate on 2026-09-06 read zero on all three success paths: a stranger charge, a checkout start, or an affiliate event. The demand-test kill on 2026-09-03 had already fired at 0 paid orders.
I have a standing rule for this fleet. More output is only good when it reduces stress, increases freedom, protects the capital engine, or creates useful work for real people. If an agent loop creates more work than it removes, it is failing even when it ships artifacts. 143 PRs and zero dollars is that sentence with a scoreboard attached.
What does the industry number say?
VentureBeat reported Faros AI figures on the software-factory thesis. Task throughput per developer was up 33.7 percent. PR merge rate was up 16.2 percent. The incidents-to-PR ratio was up 242.7 percent. Bugs per developer were up 54 percent. Google's DORA research associated more AI adoption with worse delivery stability.
Those are not my fleet's incident counts. I am not going to pretend they are. They are the shape of the same mistake: counting the cheap half of the loop.
PostHog wrote on 2026-08-11 that agents write code faster than any human can review. Their own shop had agents writing about 70 percent of PRs, and humans still skimmed at least 80 percent of those. That is lights-on, not lights-off. The dunk on lights-off factories is that the review never gets cheaper at the same rate as the generation.
I already have a post about empty pages that passed every schema check. This is the money version of that post. Volume is easy to count. Value is not.
What do I refuse to count as success?
Merged PRs. Agent headcount. GREEN test grids. Blog-post volume. Tokens per second. Saved-rig counts that are not strangers.
I will count paid orders, checkout starts, and time returned. I will count a kill rule that actually fires. I will count a model that earns promotion on held-out work, not a model that merely loads.
If your factory's weekly review leads with PR count, you are grading the intern on words typed.
Accompanying prompt
What the prompt does: It splits a weekly agent report into throughput metrics and outcome metrics, and fails the week if only throughput moved.
Copy/paste this prompt:
Copy-ready prompt
Paste the exact block into your coding agent.
No article chrome, no footnotes, no formatting drift.
This prompt and every other one we publish live in the free prompt library.
Copy the block above.
If you want the next receipts from this fleet, the list is here: https://bmdpat.com/5090-reports
Get the Local AI Field Kit
Four copy-ready tools now, then one evidence-backed Local AI Lab Note on Friday when there is something worth sharing.
Try the free agent run check firstGet the requested artifact now, then at most one evidence-backed Local AI Lab Note on Friday when there is something worth sharing. One-click unsubscribe. No sponsored placements. Privacy.
Patrick Hughes
I build BMD and publish measured AI runs, failure reports, and reusable checks. Nashville, Tennessee.
More writing
- 5 min
My Local Blog Writer Drops Private Lines First
My local blog writer reads a daily log. I remove private lines before drafting, then check the output again. Here is what those checks can miss.
- 6 min
A kill rule that expires is not a kill rule
I wrote a kill rule for a paid-path test. Zero orders landed. The card expired into an archive and the dashboard still said ACTIVE.
- 6 min
My agent wrote 126 empty pages and every gate passed
One commit wrote 130 knowledge pages. 126 were the same four sentences with the title swapped. Schema checks, link checks and orphan checks all passed.
- 4 min
Your AI Agent Says "Done." Make It Prove It.
AI agents report work as done that they never did. Make every completion a falsifiable claim a script can verify before you trust it.
- 5 min
Ollama JSON: Empty Results Are Not Failed Requests
An empty Ollama result can mean no matches or a broken request. I test the response parser so local extraction failures cannot pass as clean results.