My agent roadmaps did not prove the work was done
I wrote agent roadmaps, but my September 18 records showed a separate problem. Plans, delivered work, and saved time each need their own evidence.
I wrote more plans than I could prove finished on September 18, 2026. My devlog put new roadmaps beside an aborted nightly sweep. Both happened. One did not cancel the other.
Summary: On September 18, 2026 I published new agent roadmaps beside an aborted nightly sweep. The four plans listed 24, 25, 28, and 28 cards, and those cards are planning artifacts, not finished work. The same record had a delivered email to seven subscribers, a live blog post at 11:37, and no measured saved minutes.
A roadmap records possible work and its dependencies. It does not authorize an agent to start every task. It also cannot prove delivery or time saved. My September 18 record had evidence for some deliveries, but no measured saved minutes.
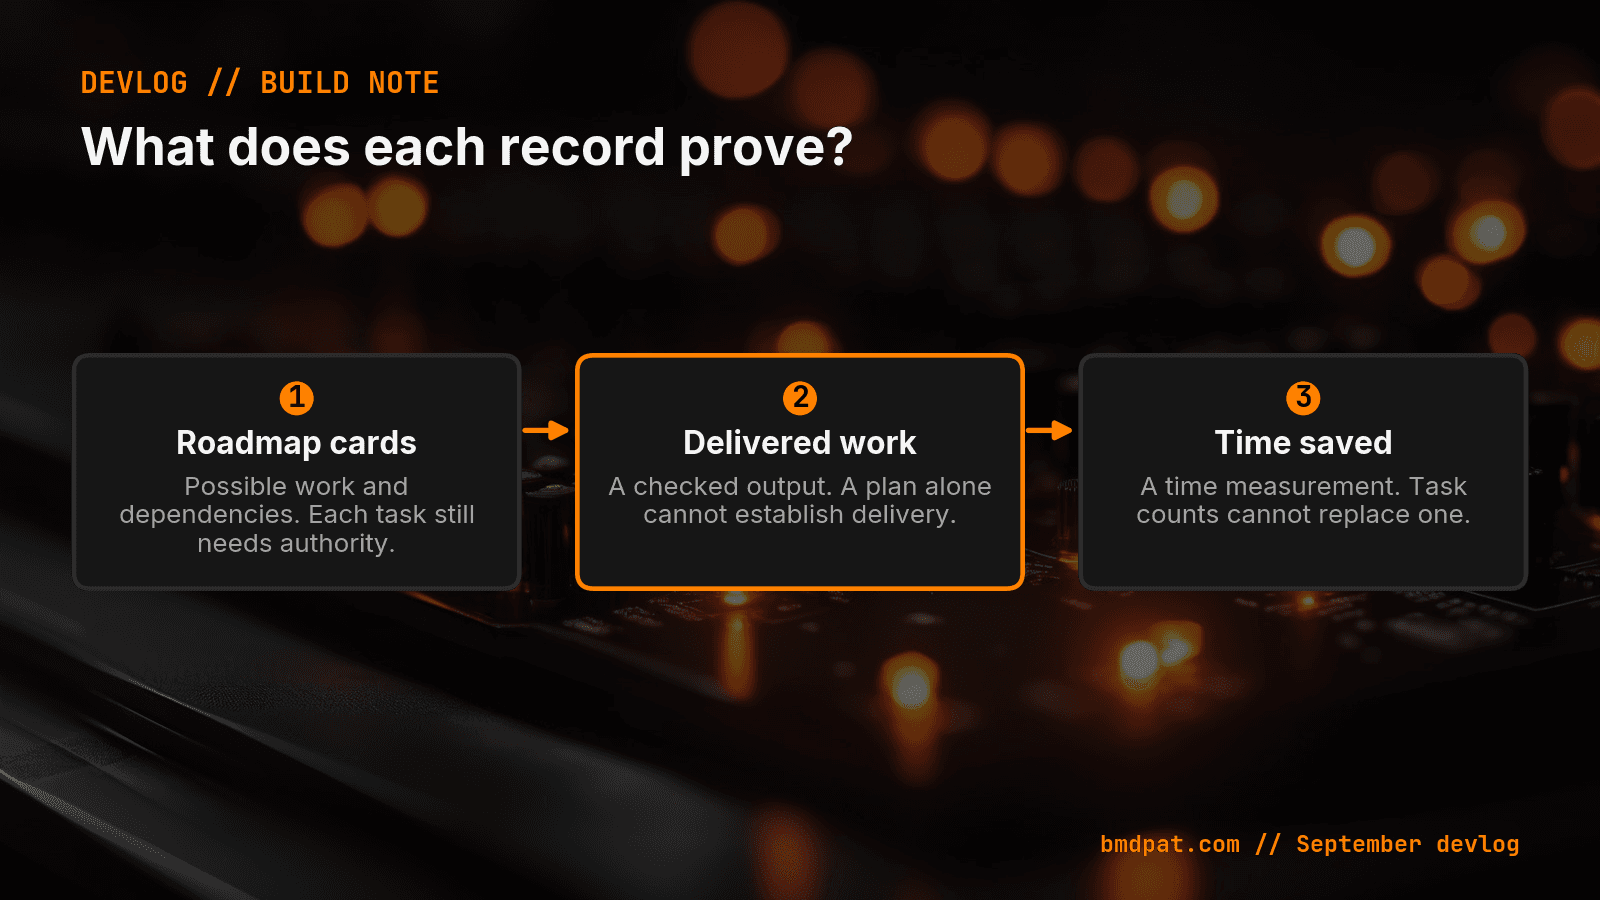
What did the roadmaps actually establish?
The Brain roadmap had 24 unassigned backlog cards. The website roadmap had 25 planning cards. AgentGuard had 28 unassigned backlog cards. The showwork plan had 28 child cards.
Those counts describe planning artifacts. I cannot add them together and call the result shipped features. An unassigned card still needs someone to take it. A dependency still needs the work on the other side of it to finish.
The plans also carried weekly windows or targets. That gave the work an order. It did not prove that the dates would hold. My devlog recorded the plans as published, which is a valid result for a planning task. It is a narrower result than finishing the work inside them.
The choice behind the plans was simple. I wanted work across Brain, BMD, AgentGuard, showwork, and the website to improve the other work. Each product still had its own job. The plans described possible work. They did not give every agent permission to start it.
That last sentence matters when a machine can turn a list into actions. I need the plan to explain what could happen. I need the owning task to say what may happen now.
What evidence did I have for delivery?
The AgentGuard v1.3.2 release email had a different kind of record. I approved it after a delivered owner test. The September 18 devlog says all seven active subscribers received the announcement. A retry sent no extra messages.
That is evidence about an email. It does not show that seven people installed the release. It does not show that anyone read the message or wanted another product. I can report the delivery without adding a demand claim.
The blog had a separate result. After several failed runs, Codex and the publisher reached a live article at 11:37. The live page was the outcome. The failed runs still belonged in the record because the publishing path needed them before it worked.
I had already written about checks that prove what my agents did. September 18 made the distinction concrete again. A published plan, a delivered email, and a live article each answer a different question.
What remained unproven after those results?
The nightly sweep for September 17 had aborted when its sandboxed process exited without a report artifact. That missing report stayed missing in the September 18 record. A new roadmap could not supply it.
The same record listed one completed Brain Worker task, zero rerouted tasks, and three skipped tasks. I cannot turn the skipped tasks into completed work by describing the whole run as productive. Each result needs to keep its own status.
My sandbox repair post covers the related boundary: passing command checks did not prove a later full run. I still need evidence from that full run before changing the claim.
The time-return report had no explicit saved minutes. That does not mean the work saved zero minutes. It means I did not have a number I could defend. I left the uncertainty in the devlog instead of using the size of the roadmap as a substitute.
Which check in your agent report proves the work finished?
Accompanying prompt
What the prompt does: Separates planned work, checked outcomes, and unmeasured claims in a daily agent report.
Copy/paste this prompt:
Copy-ready prompt
Paste the exact block into your coding agent.
No article chrome, no footnotes, no formatting drift.
This prompt and every other one we publish live in the free prompt library.
Copy the block above.
See how I run the agent fleet: https://bmdpat.com/bmd
Get the Local AI Field Kit
Four copy-ready tools now, then one evidence-backed Local AI Lab Note on Friday when there is something worth sharing.
Try the free agent run check firstGet the requested artifact now, then at most one evidence-backed Local AI Lab Note on Friday when there is something worth sharing. One-click unsubscribe. No sponsored placements. Privacy.
Patrick Hughes
I build BMD and publish measured AI runs, failure reports, and reusable checks. Nashville, Tennessee.
More writing
- 4 min
My sandbox passed two tests. The full run was unproven.
I repaired a Windows agent launcher on September 17. Shell commands and two tests passed. That still did not prove the whole nightly queue could finish.
- 5 min
Gemini first for four jobs. One run finished two tasks.
I moved four recurring jobs to Gemini, then checked what actually finished. One recorded run proved progress. The broken queue sweep stayed broken.
- 6 min
143 pull requests. Zero dollars.
In the week of 2026-08-31 the fleet merged 143 product pull requests. Stripe still read zero. Throughput is the tell, not the win.
- 6 min
A kill rule that expires is not a kill rule
I wrote a kill rule for a paid-path test. Zero orders landed. The card expired into an archive and the dashboard still said ACTIVE.
- 6 min
My agent wrote 126 empty pages and every gate passed
One commit wrote 130 knowledge pages. 126 were the same four sentences with the title swapped. Schema checks, link checks and orphan checks all passed.