A green check lied, so I built append-only status
On 2026-09-25, a false green report buried a real fix. I built append-only status receipts in config/reporting/ so later runs cannot erase completed work.
On 2026-09-25, a green report lied to me after a blog recovery worked. A later no-op report buried the fix. That false green is what I spent the day on. I put the repair in config/reporting/ across four commits: 42dfa07b6, b75ad7036, f94294a40, and 23879a4c5.
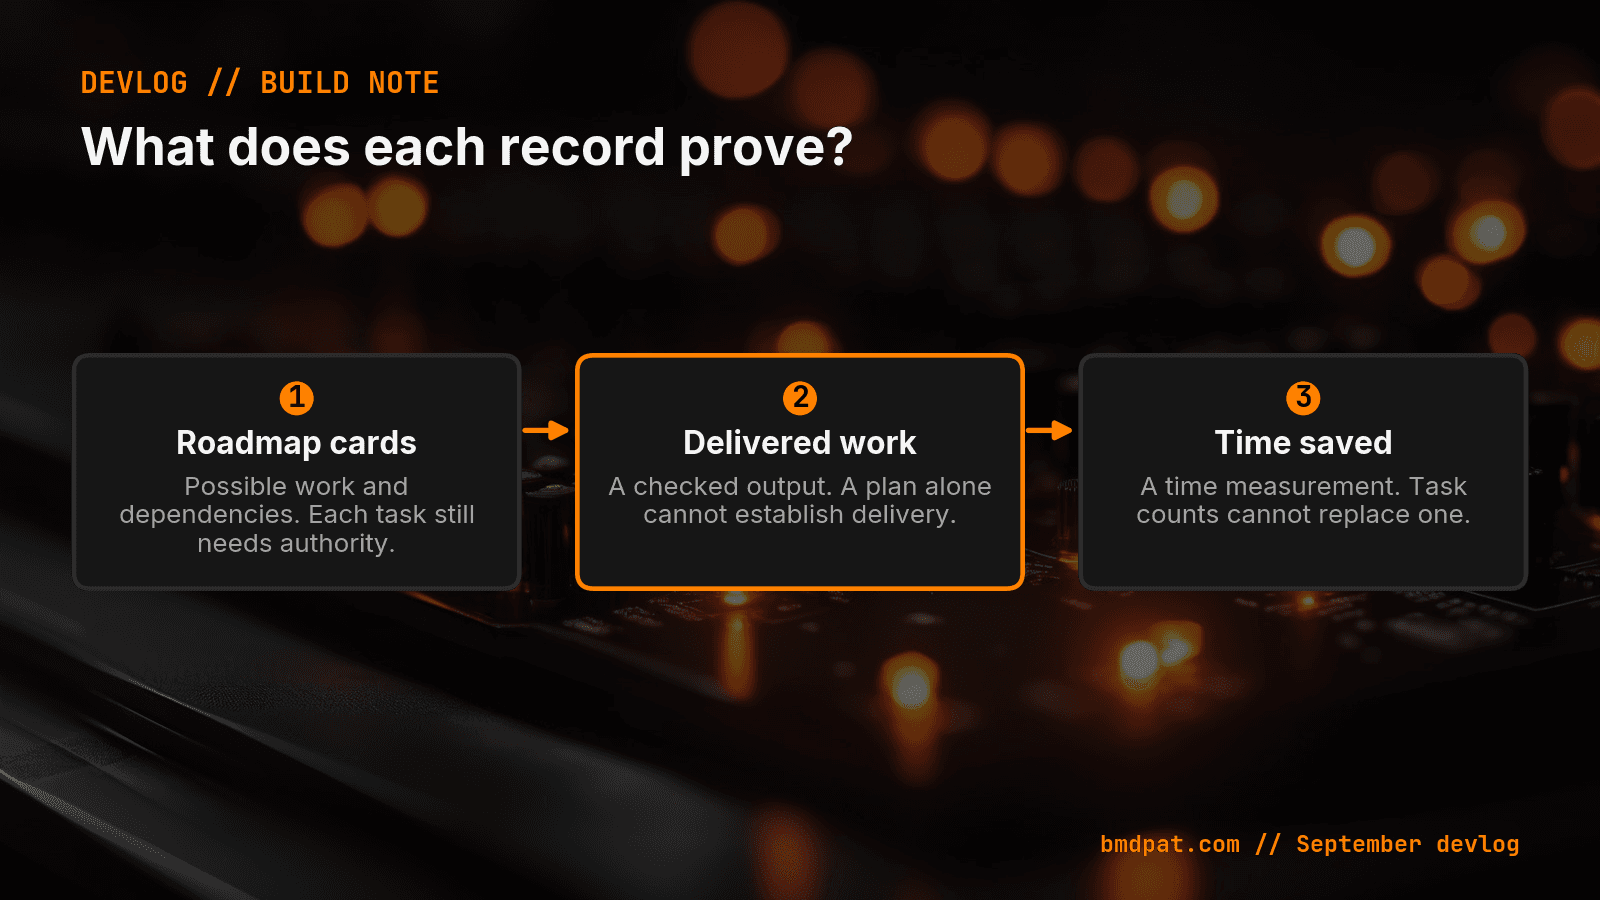
Why did a green test report lie about my build?
A green test report lies when a pass signal records absence of a crash instead of positive proof. On 2026-09-25, my sweeps showed green while checks inspected zero files. A reporting layer must demand explicit receipts before it declares any job healthy.
SecurityAnalyst marked its scan GREEN with 0 P0 and 11 P2 issues. But gitleaks and osv each read 0 of 5 repos. That unaudited GREEN did not cover five critical findings a separate dependency audit found in bmdpat and agent47-dashboard. Repair PRs 1629, 1724, and 271 sat undecided.
The sweep aborted before dispatch after 22 minutes. An environment listing exposed the Brain signing credential. Zero cards attempted, 45 skipped. Credential P0 hit 19 days. Vault health stood CRITICAL with six staged Outbox drafts past TTL. Across 1,027 ledger rows, 44 failed, with pi-researcher-sync taking 19. The full suite sat RED at 552 of 553. Devlog-daily failed on 2026-09-24 after three attempts.
Brain worker 21:11 shipped 4 items, 0 to patrick/. Loops had 451 sessions, 5 CTA clicks, and zero install intents. In BMD, see what your agents actually did, you track real action instead of assumptions. You must verify what an agent actually produced before trusting a report. Missing evidence is unknown, not green.
How do you stop a later job from burying a real fix?
You stop later jobs from erasing fixes by storing append-only event receipts instead of mutable state. When each run writes an immutable log, no failed attempt can delete earlier progress. Your status engine can then project health without rewriting history.
I built config/reporting/ to enforce this rule. It writes append-only receipts on the existing Reports/Events/ authority. Markdown files become generated views, never input for status decisions. I recorded the decision in Knowledge/decisions/2026-09-25-shared-reporting-contract.md.
When you give an agent a file, not a memory, you keep receipts that survive bad runs. That design allowed me to close two real false greens on 2026-09-25:
| Commit | Bug Cause | Old Behavior | Fixed Result |
|---|---|---|---|
746c7dff0 | Public readback mixed title and text | 3 of 24 cases false green | 128 pass |
3910b02a3 | Malformed falsey deadline disabled check | 7 of 14 cases failed silently | 14 pass |
What happens when a fuzzer tests your reporting layer?
A fuzzer exposes edge cases by feeding millions of malformed records into your replay parser. On 2026-09-25, my fuzzer ran three million generated inputs across ten seeds. It killed every seeded mutant. The parser held on that generated set.
I pointed the fuzzer directly at config/reporting/. It ran 3,000,000 cases over 10 seeds on malformed inputs and replays with zero failures. Ten seeded mutants were all killed. The engine replayed 10,000 receipts in 0.44 seconds.
I wanted eight nines of reliability. I got 3,000,000 cases without failures. But generated fuzz tests are not production trials. The test receipt records that limit. Bonsai 27B vs Gemma 4 E4B went live at HTTP 200 with two dev.to cross-posts. On bmdpat, PR #1836 and docs PR #1839 merged to match accessible names rather than decorative glyphs.
Who I was on 2026-09-25
I asked for a permanent repair after a later report hid a real blog recovery. The result was a shared reporting tool. It keeps the completed work, the latest attempt, and current health separate. I want to read the record without reconstructing the day myself.
I named the failure I wanted to reduce: incorrect status, especially false green. The Codex test receipt records three million generated cases without failures. It also leaves production reliability unmeasured. That limit belongs beside the number. SecurityAnalyst still called its scan GREEN after reading zero of five repositories. A better reporting tool does not repair every report that came before it.
I made the same call twice on 2026-09-25, at two sizes. On bmdpat #1836 I said the arrow glyph is intended, so repair the test helper and leave the card alone. When a check disagrees with the thing it measures, I fix the check.
I also read the X and LinkedIn drafts for BMD and held them. I said I needed to spend 2026-09-26 really using it. Clean copy did not settle whether I was ready to put my name behind the release.
On 2026-09-25 I changed how the machine records proof. I also left myself a test that no agent can finish for me: use BMD before I announce it.
What should you do with this?
You can protect your own pipelines by decoupling event recording from status presentation. First, record every action as an append-only receipt. Next, reject passing grades whenever scanners inspect zero targets. Finally, recheck your failure logs before you trust any green dashboard.
- Separate event storage from status views. Write raw receipts to disk. Generate summary views only as downstream projections.
- Require positive proof of scanned targets. If a scanner reads zero files, mark the run as unknown instead of green.
- Fix test assertions when they disagree with reality. Update the test helper rather than breaking working UI.
Accompanying prompt
What the prompt does: Audits your test suite or reporting jobs for false green status claims caused by unread targets or disabled checks.
Copy/paste this prompt:
Copy-ready prompt
Paste the exact block into your coding agent.
No article chrome, no footnotes, no formatting drift.
This prompt and every other one we publish live in the free prompt library.
Copy the block above.
Weekly measured local runs: https://bmdpat.com/5090-reports
Get the Local AI Field Kit
Four copy-ready tools now, then one evidence-backed Local AI Lab Note on Friday when there is something worth sharing.
Try the free agent run check firstGet the requested artifact now, then at most one evidence-backed Local AI Lab Note on Friday when there is something worth sharing. One-click unsubscribe. No sponsored placements. Privacy.
Patrick Hughes
I build BMD and publish measured AI runs, failure reports, and reusable checks. Nashville, Tennessee.
More writing
- 5 min
Bonsai 27B vs Gemma 4 E4B: Which Should You Run?
Compare Ternary Bonsai 27B and Gemma 4 E4B for local AI. See VRAM footprints, multimodal support, benchmark scores, and run commands for your setup.
- 4 min
I built refusals into my claim recorder
On September 23, I added write-time checks to my agent claim recorder. Six bad rows needed retraction. Here is what those checks can and cannot prove.
- 5 min
Ten Merges, One Dead Disk, Four Fake Green Signals
On 2026-09-19 I merged ten PRs into BMD desktop while a dead disk faked four green signals across the fleet. Here is what broke and what shipped.
- 5 min
I dropped the BMD kill date and named it flagship
On 2026-09-21, I removed the October 1st kill date for BMD. I also shipped bmd-desktop 3.47.15 and fixed a clipboard bug in bmdpat.
- 4 min
My sandbox passed two tests. The full run was unproven.
I repaired a Windows agent launcher on September 17. Shell commands and two tests passed. That still did not prove the whole nightly queue could finish.